Share your model with keys and limits
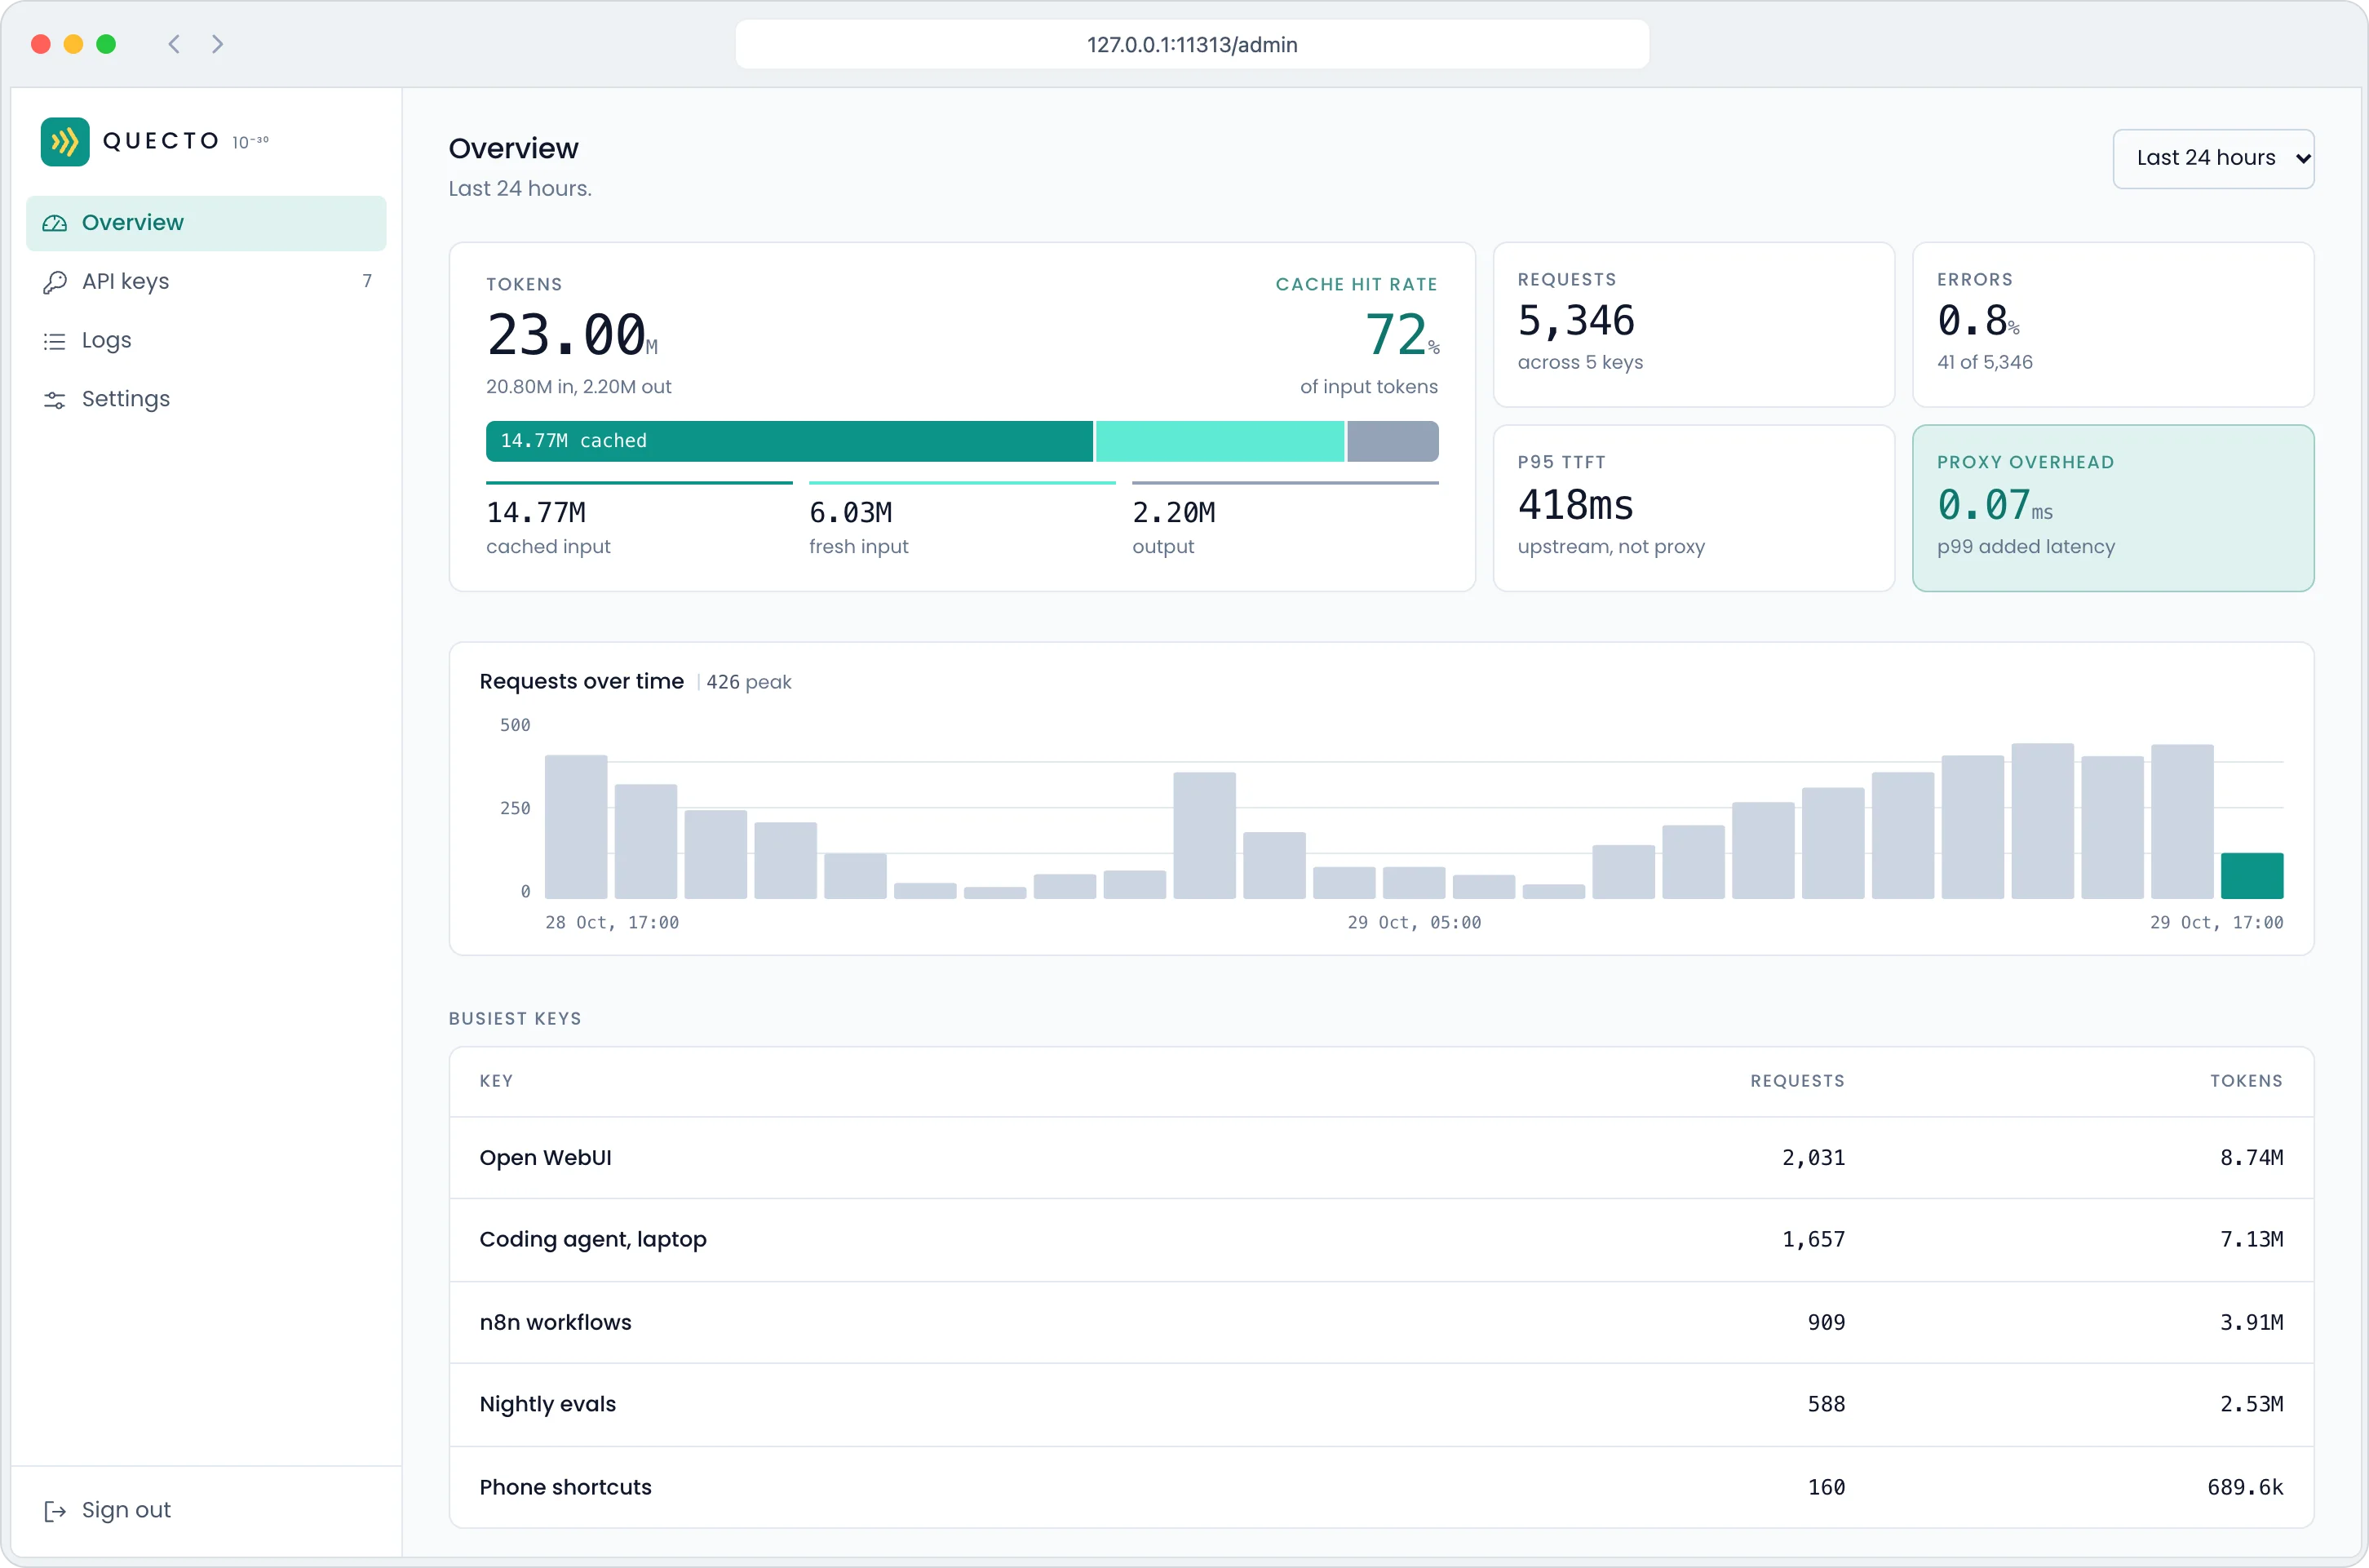
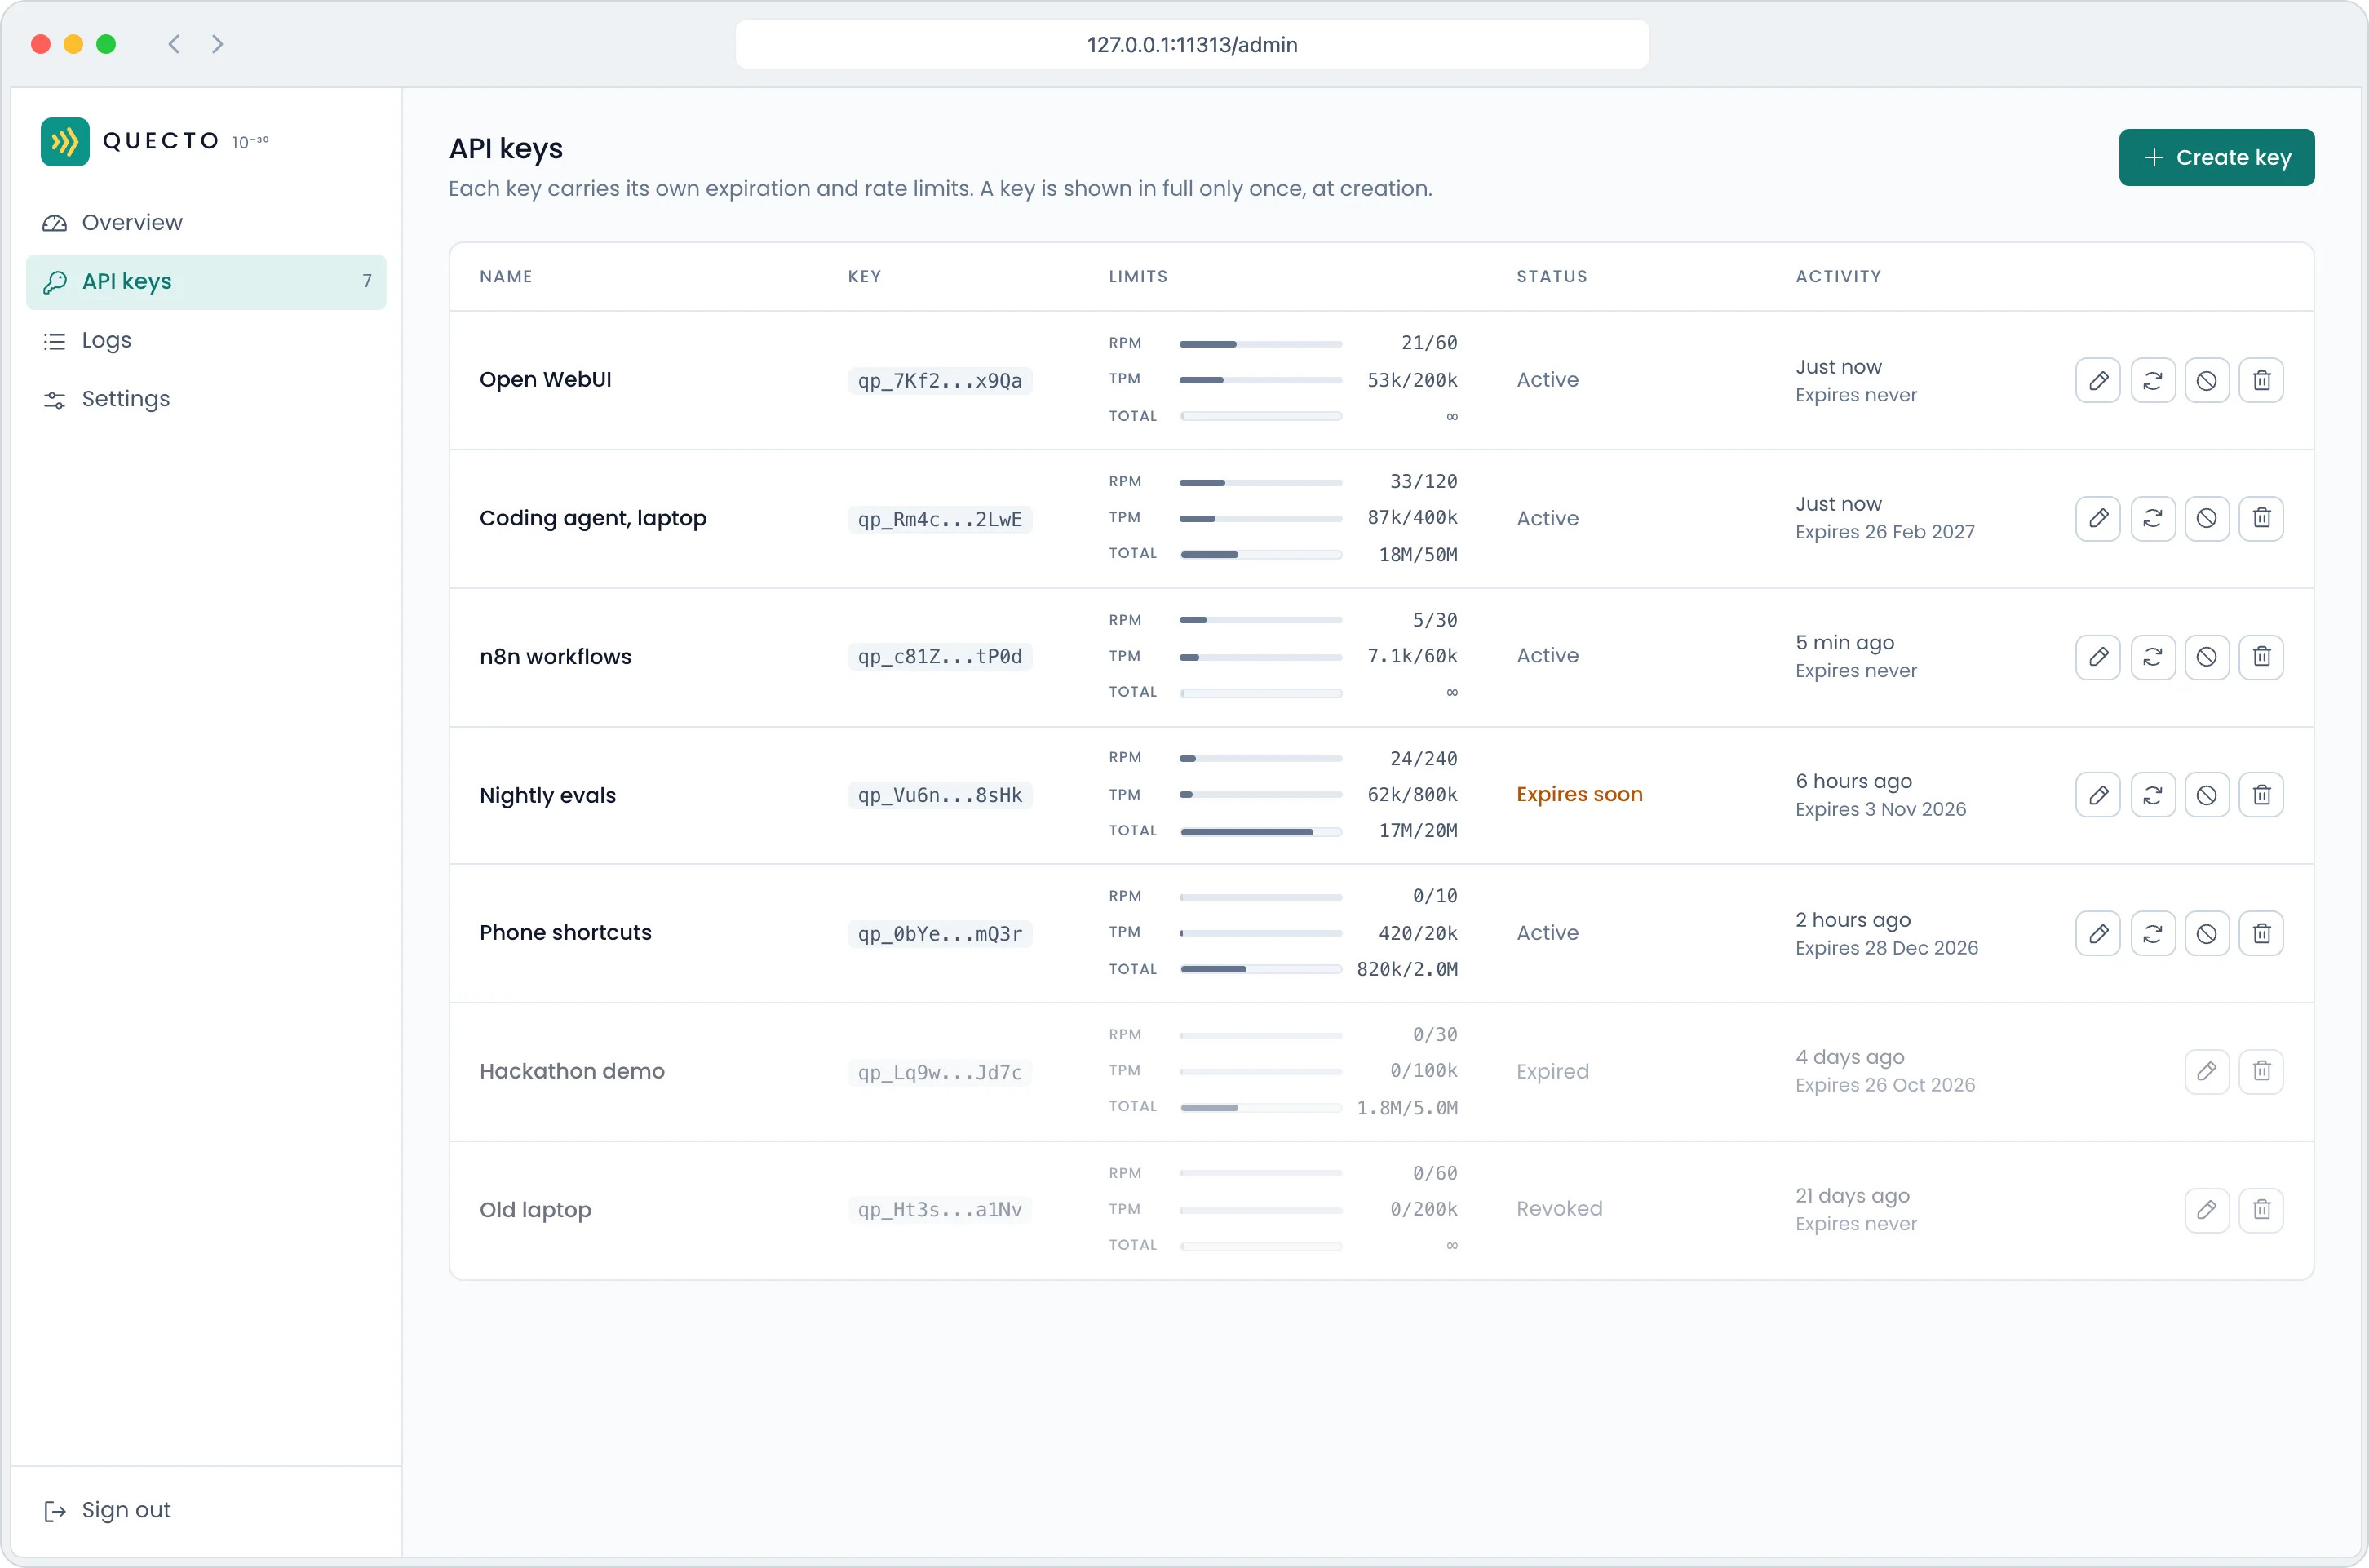
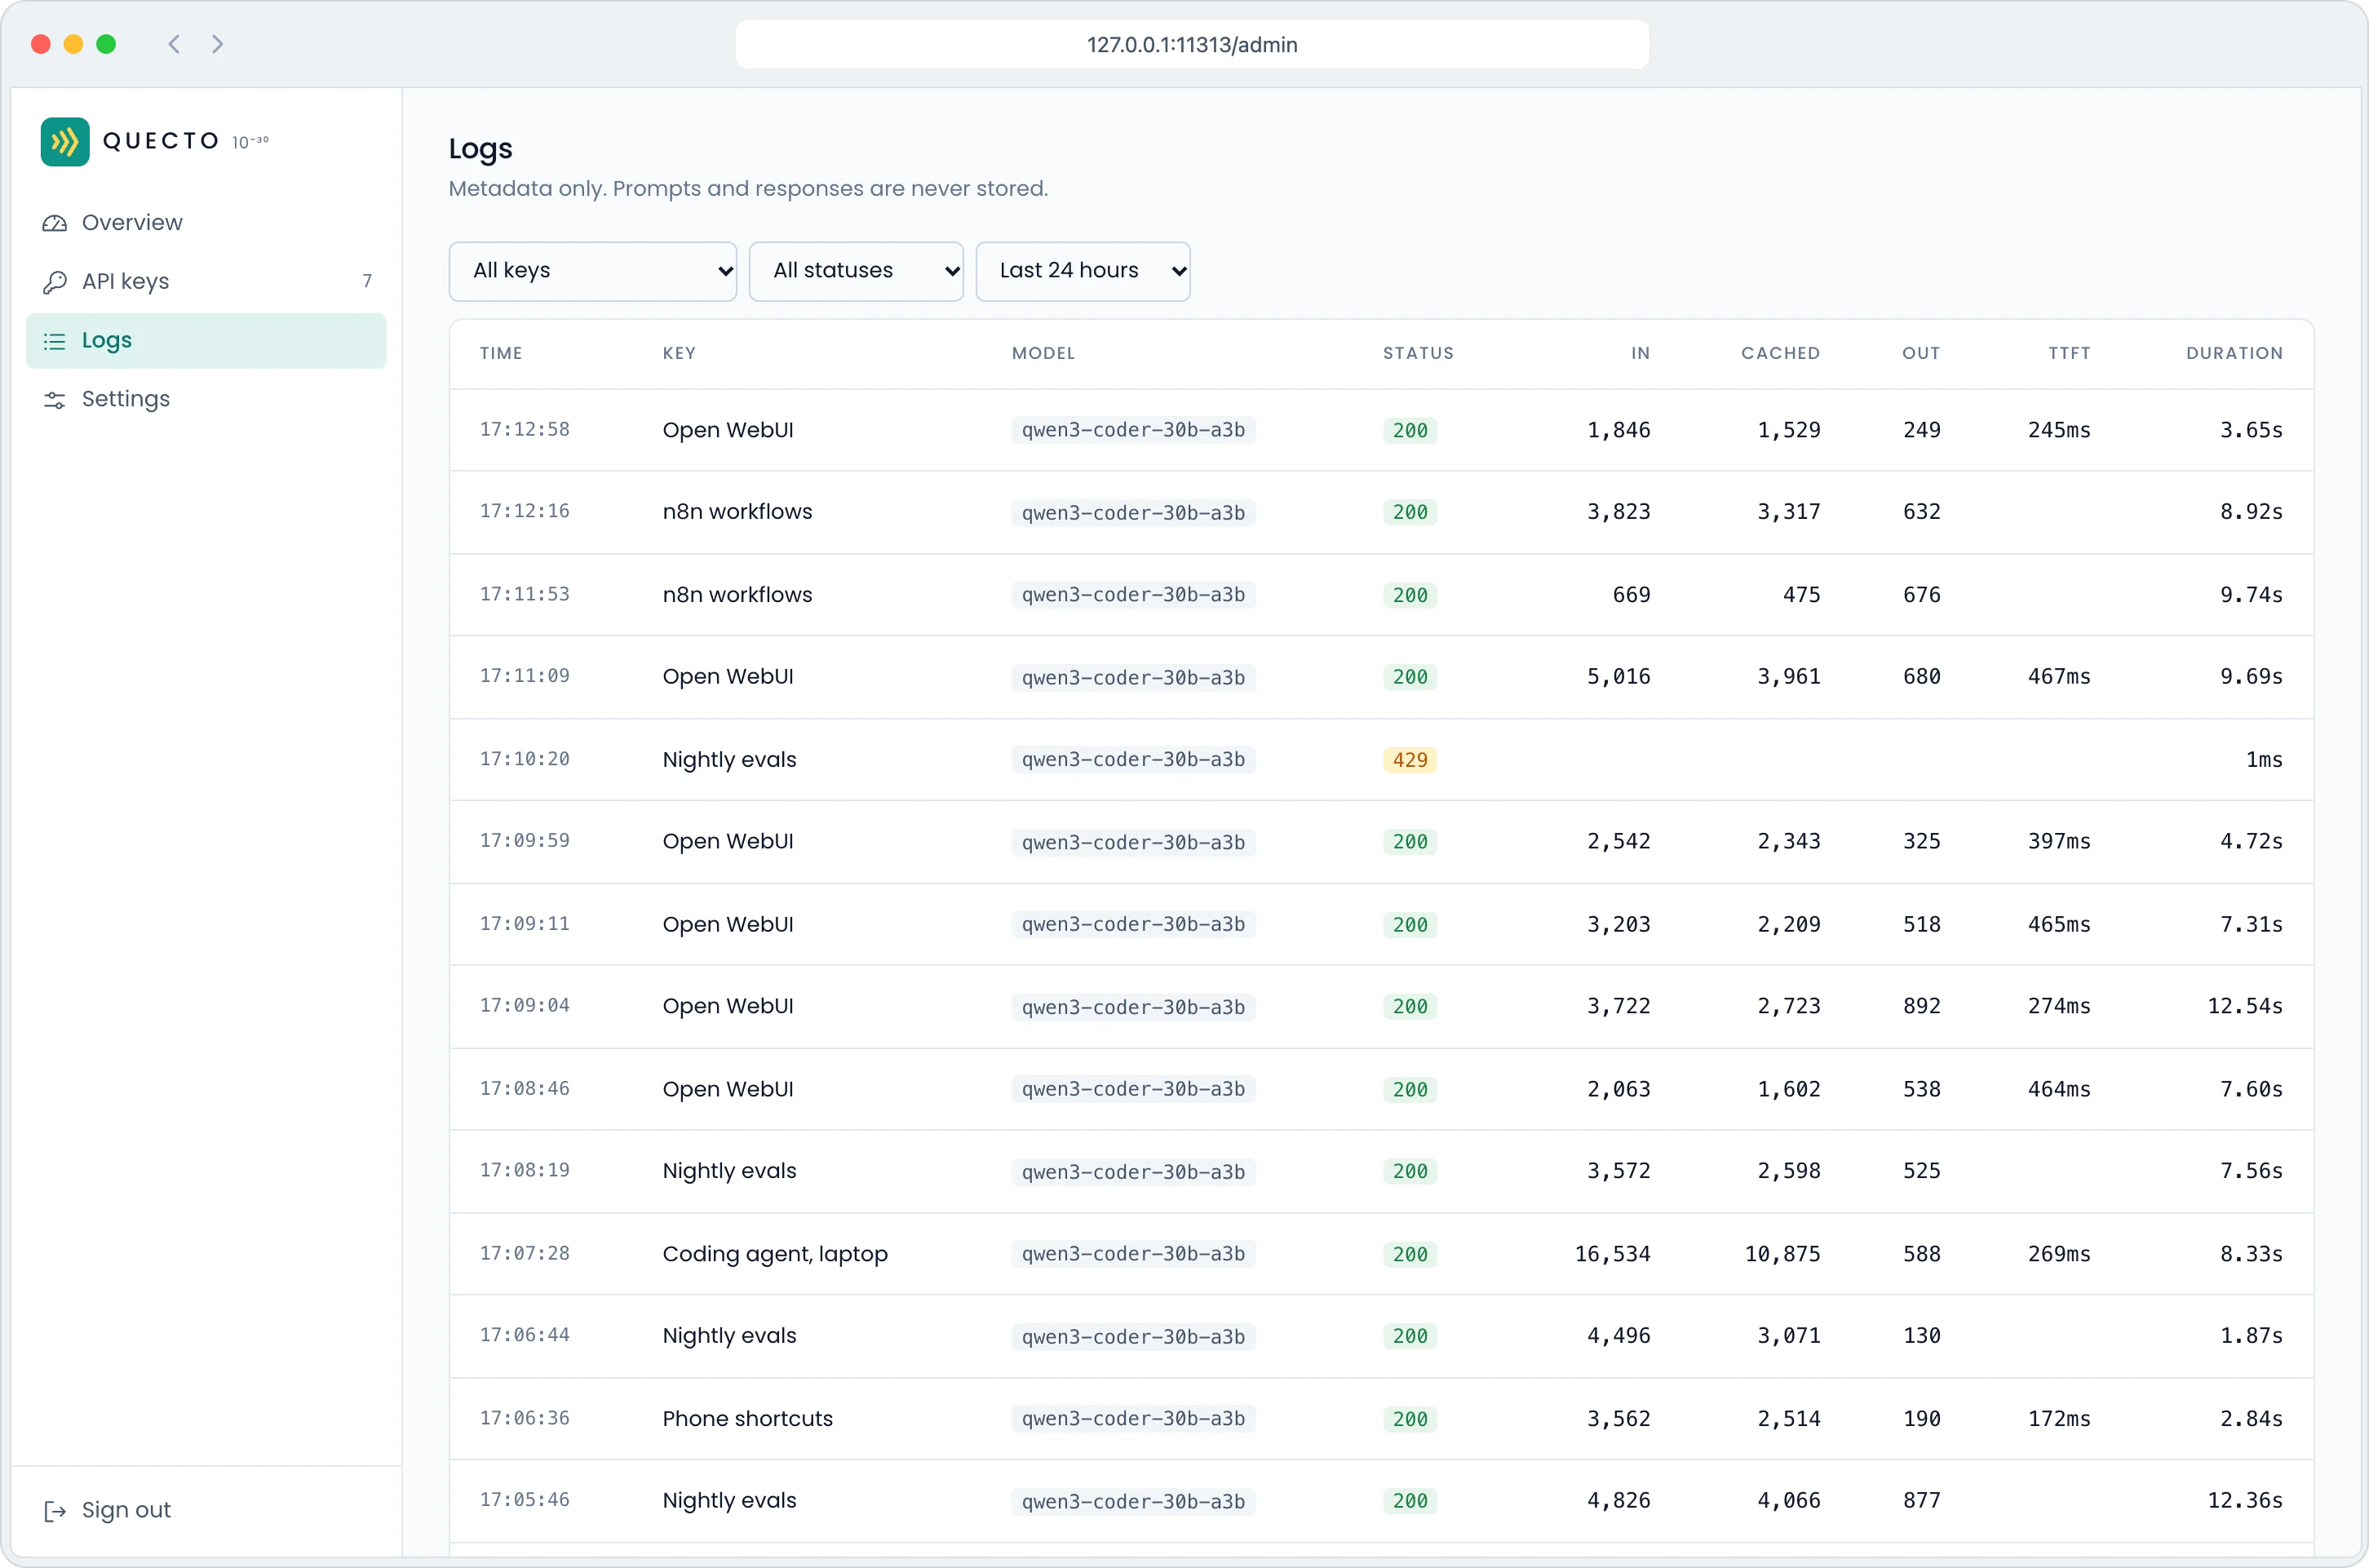
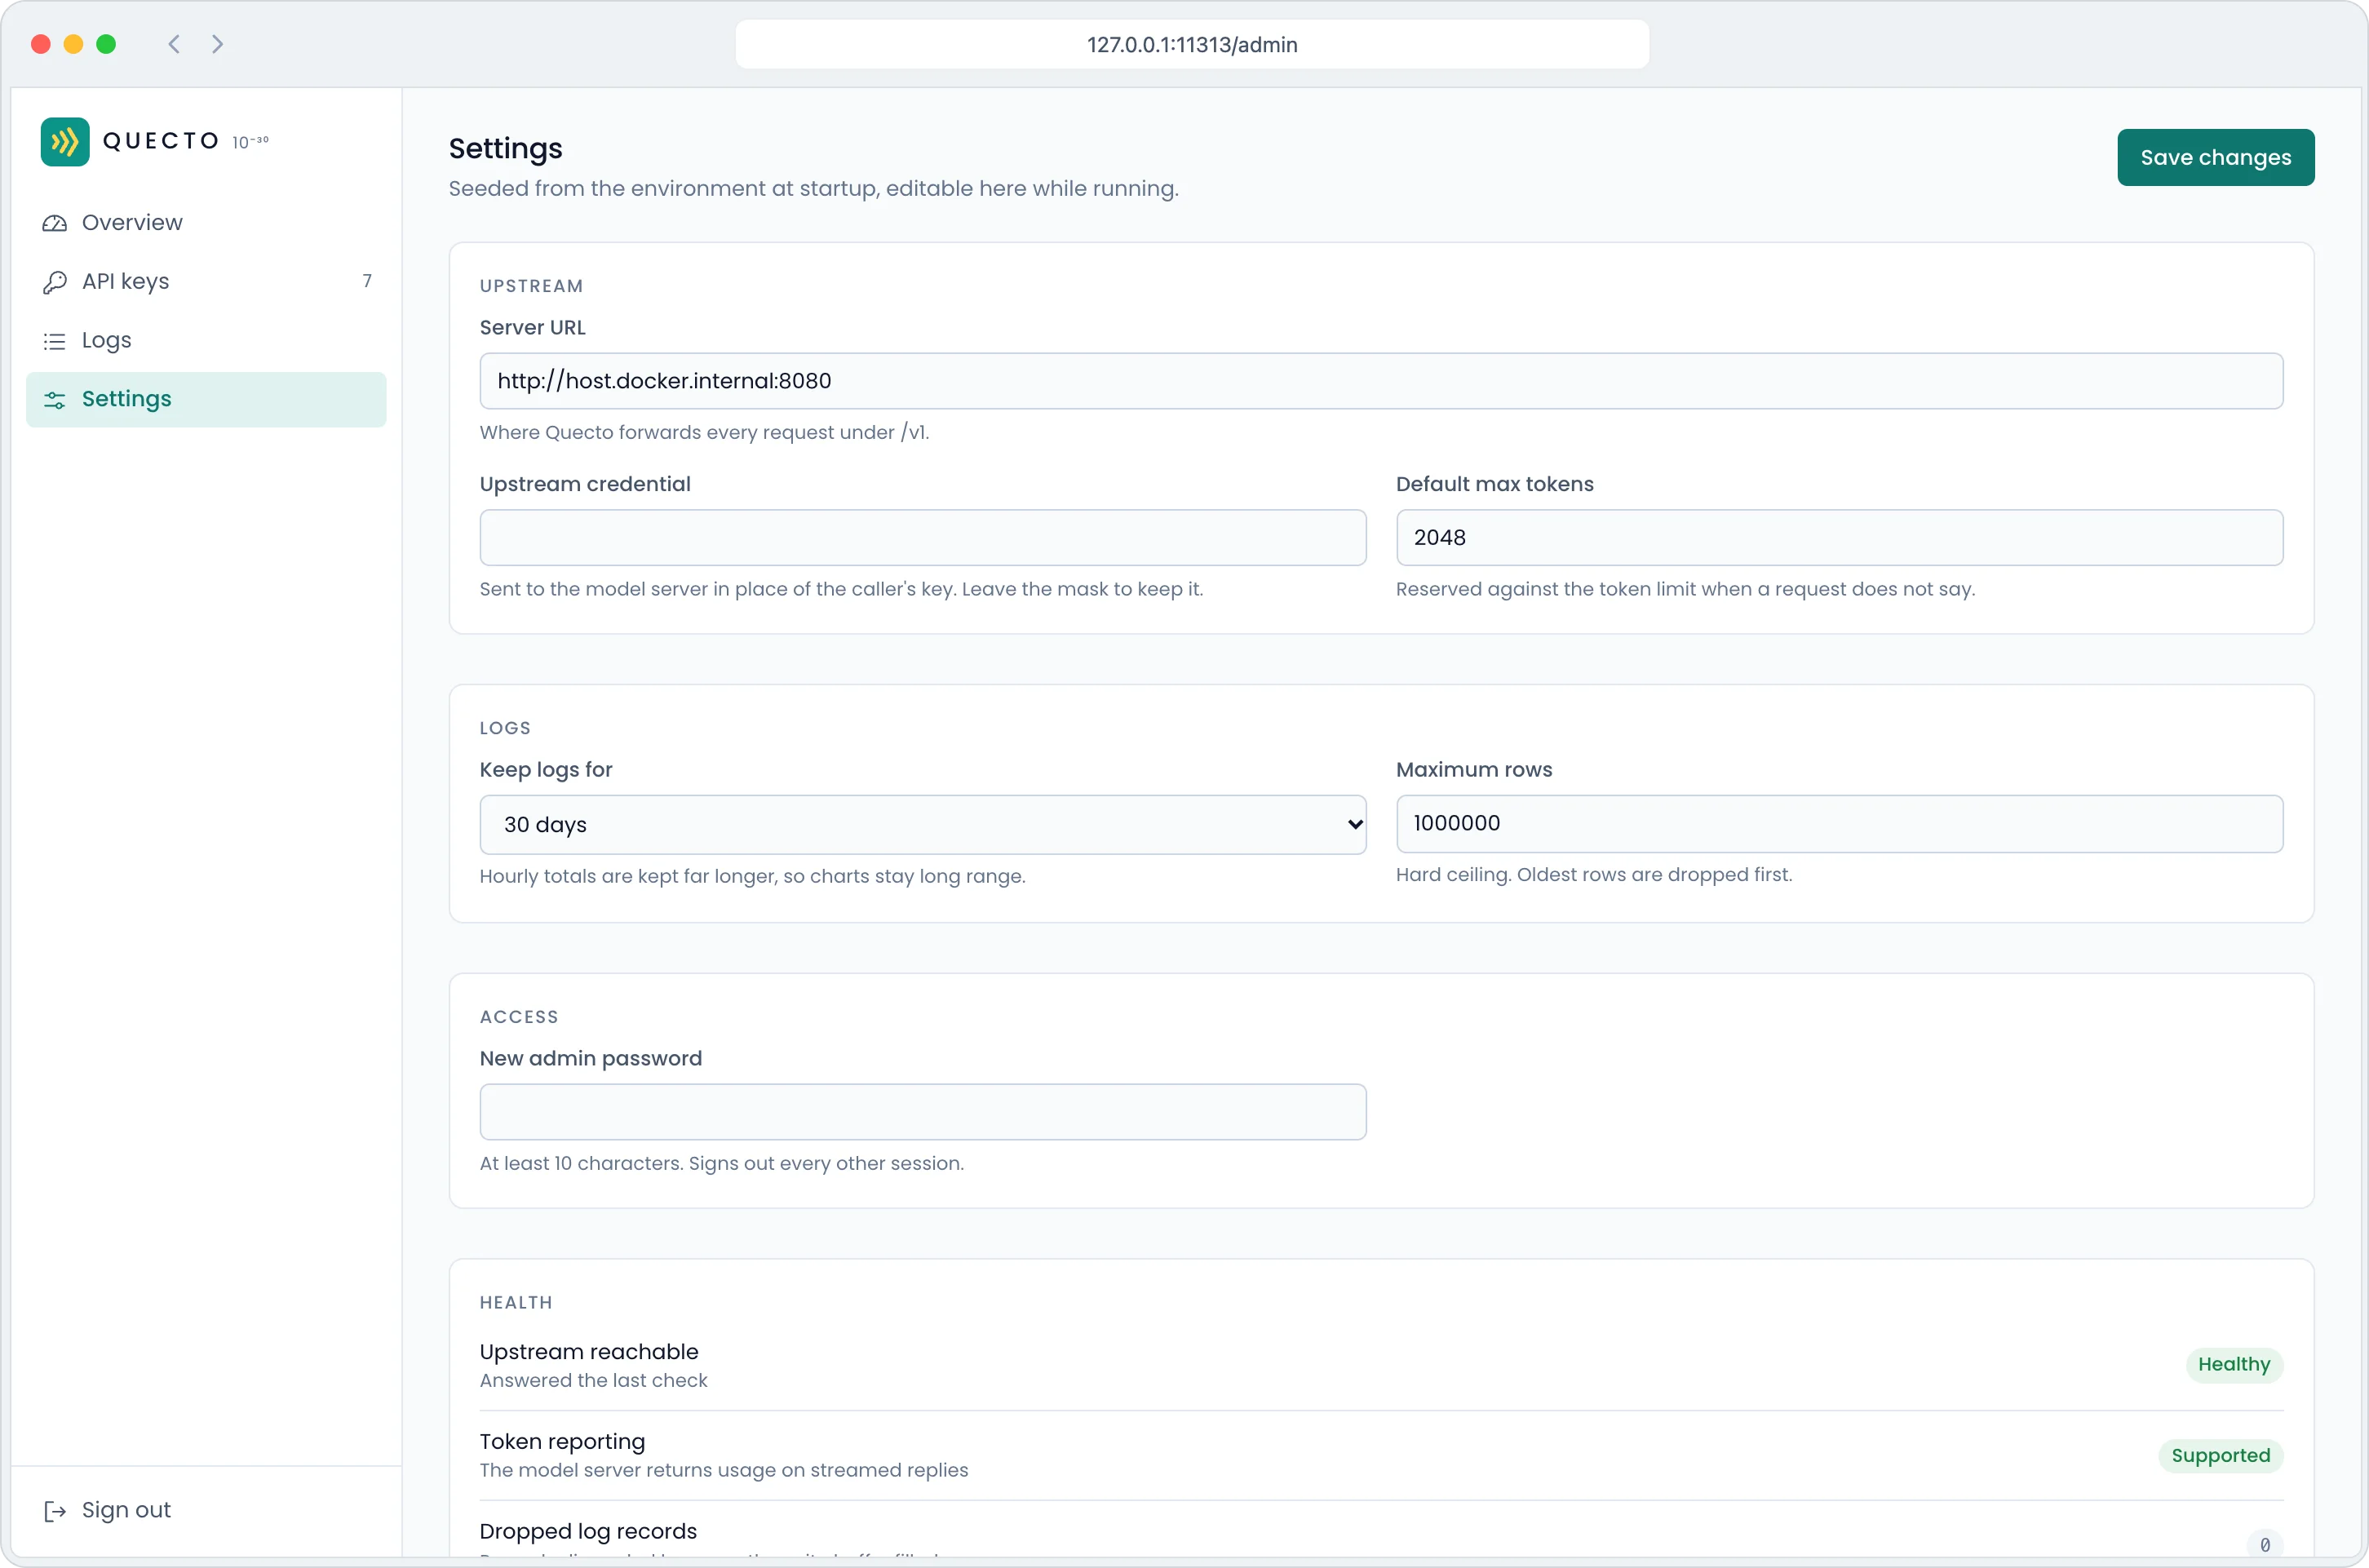
Put it in front of a model server you run, give each person or app its own key, and see who used what. Conversations are never stored.
How to start
You need Docker and a model server it can reach, such as llama.cpp, vLLM or Ollama.
Run it with Docker
Make an admin password, keep it somewhere safe, then start it.
git clone https://github.com/jesdga95/quecto-proxy && cd quecto-proxy
echo "QUECTO_ADMIN_PASSWORD=$(openssl rand -base64 24)" > .env && cat .env
docker compose up -d --build
Connect an app
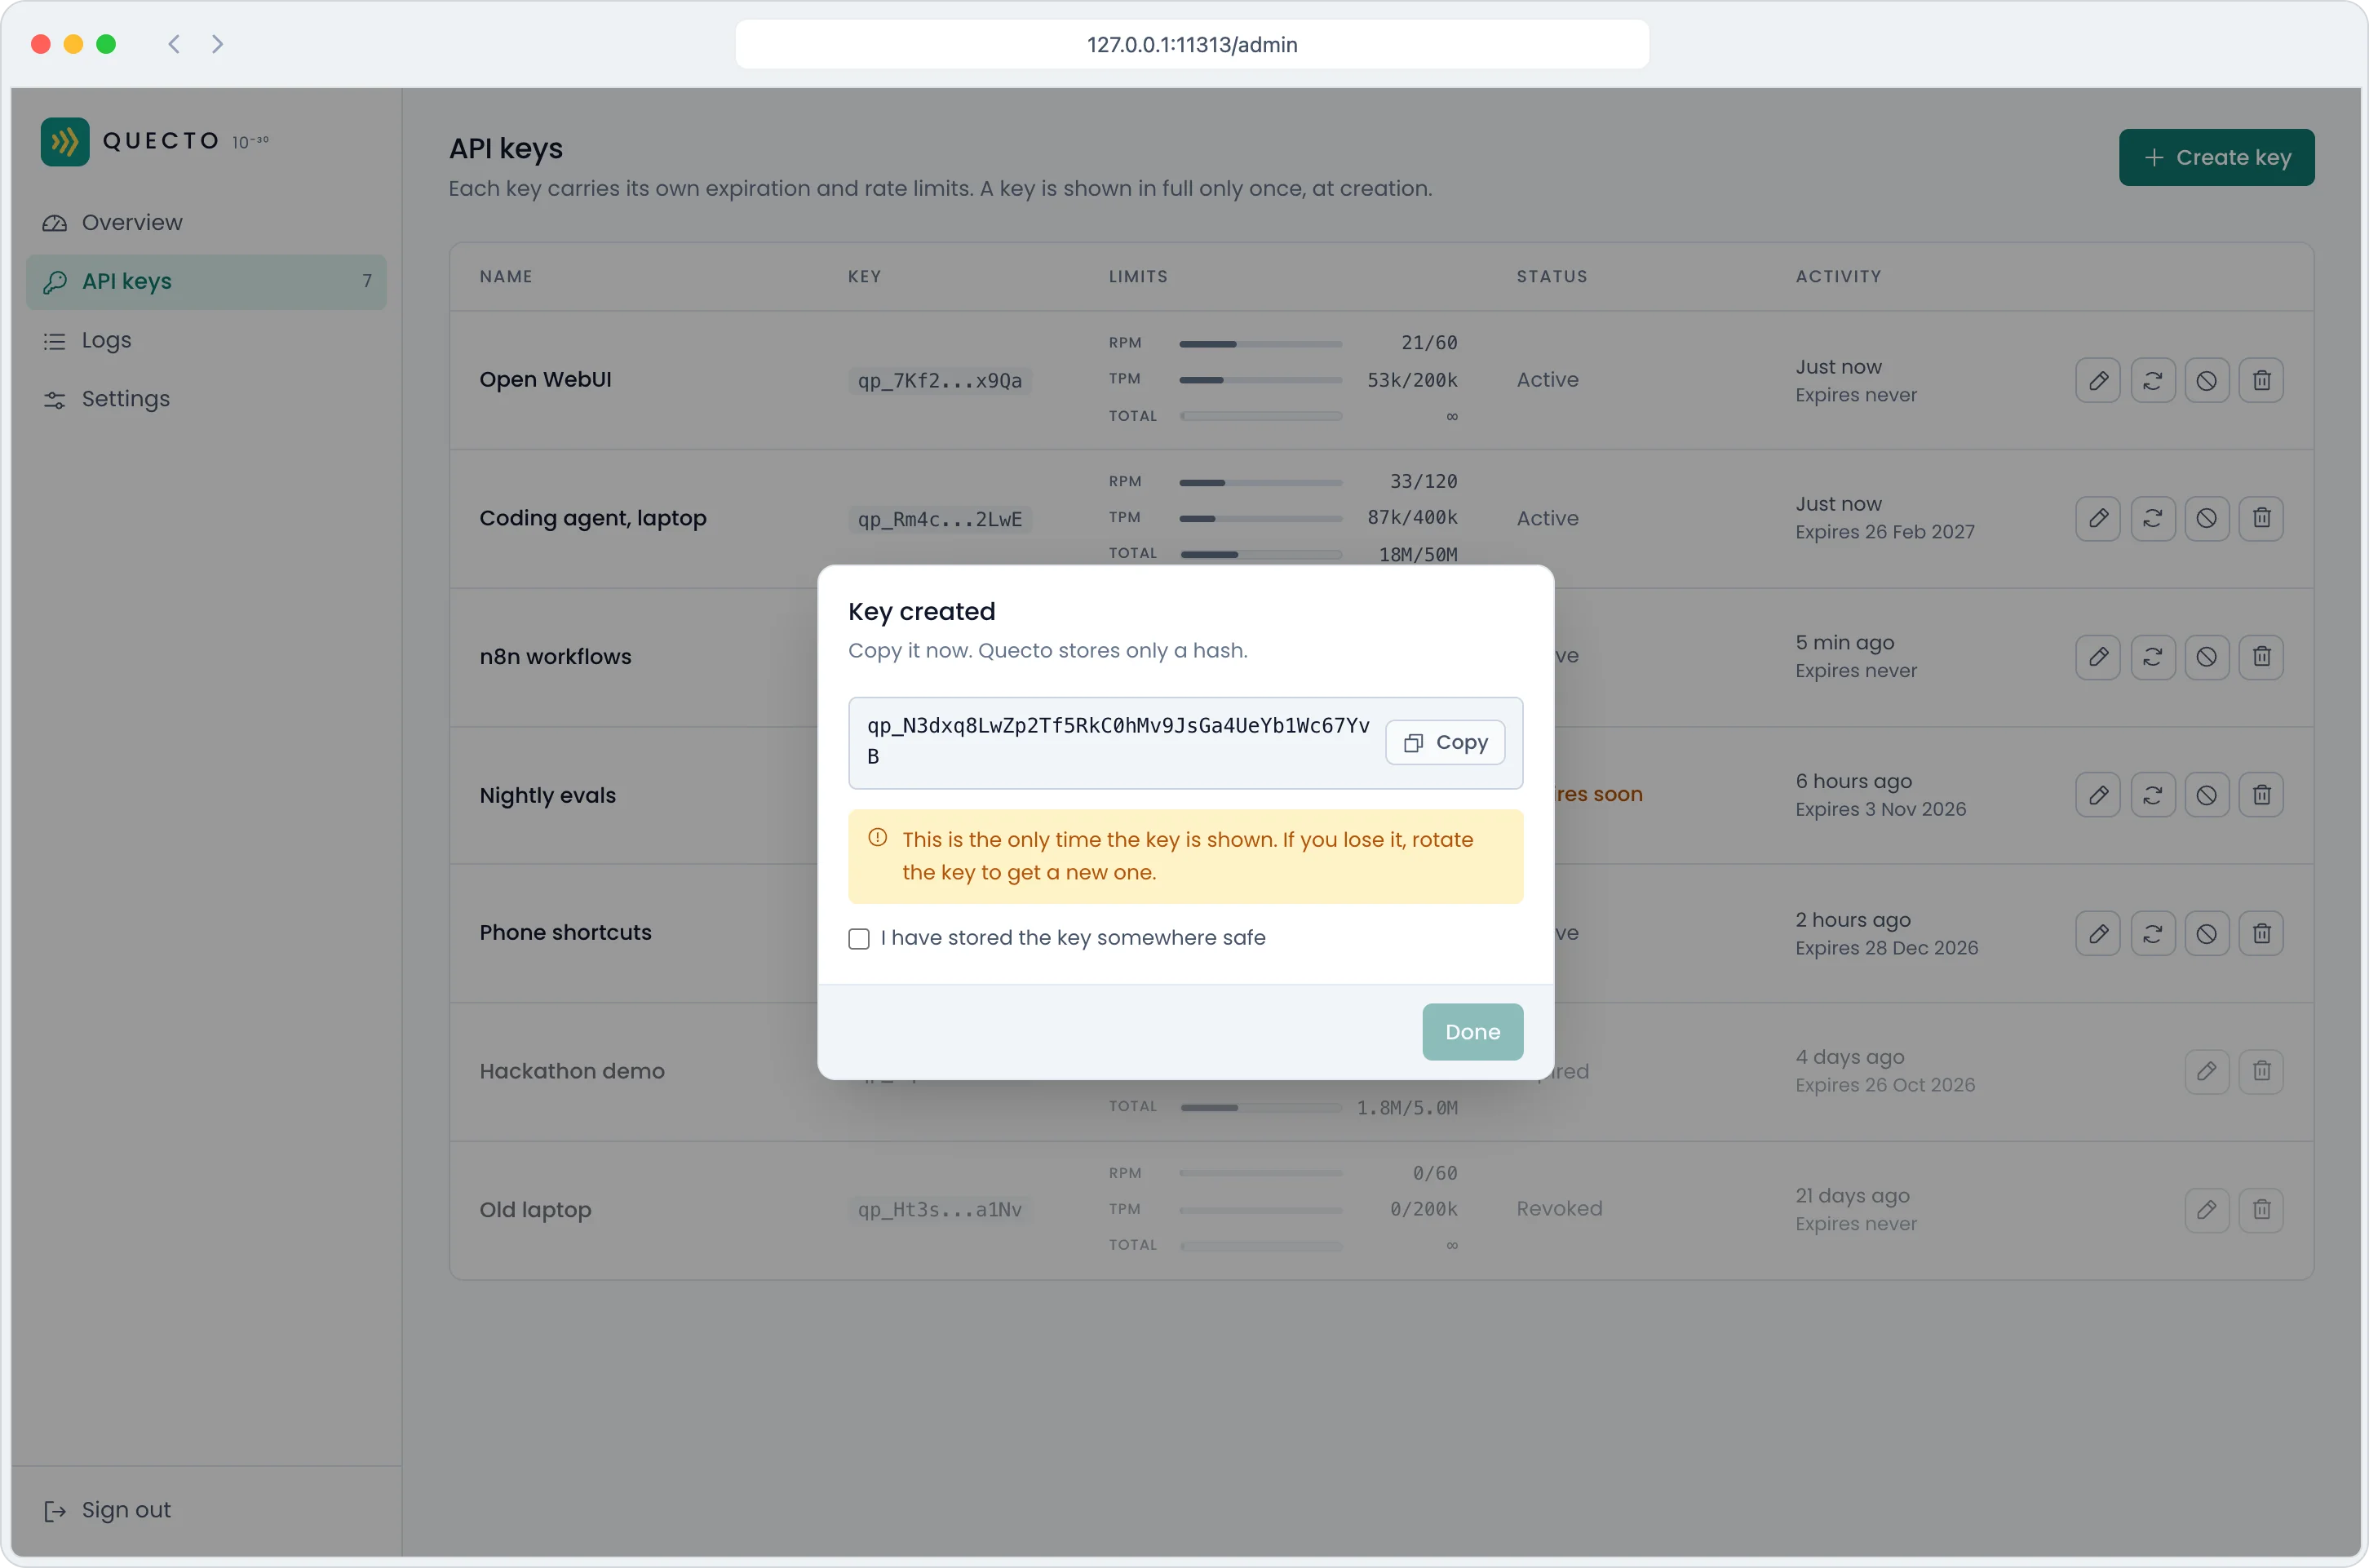
Sign in at localhost:11313/admin and make a key. Then give any app that speaks the OpenAI API this address and the key.
http://your-host:11312/v1
Free and open source
Quecto Proxy is MIT licensed. The code and the full guide are on GitHub.